Can VMware Cloud Foundation run its own AI model, keep the inference inside the private cloud, and then use that model to answer real questions about the infrastructure?
That was the question I wanted to answer in my VCF 9.1.1 lab.
The answer is yes, but getting from “I have an NVIDIA GPU in an ESXi host” to “VMware Intelligent Assist is querying my vCenter through a local Qwen model” involves much more than deploying one Kubernetes pod.
In this article, we will build the entire stack from the ground up. We will prepare the GPU, create the VM and Namespace Classes, build the correct VCF Automation networking, install Private AI Services 3.0, prepare Regional Harbor, upload Qwen2.5-7B-Instruct, create a GPU-backed ModelEndpoint with vLLM, expose it through the PAIS OpenAI-compatible API, and finally connect it to VMware Intelligent Assist in VCF Operations.
This is deliberately written as a from-zero, click-by-click lab guide. I will not only show what to configure, but also explain what it does and what you should verify before moving to the next step.
What makes this lab interesting?
The final result is not a generic chatbot. The model runs on a physical NVIDIA GPU inside the VCF environment and VCF Operations can use it together with its own tools to retrieve live infrastructure data.
Before We Start: What Is PAIS Actually Building?
If this is your first contact with Private AI Services, it helps to understand the moving parts before opening any wizard.
There are five layers involved:
- vSphere / GPU layer – the physical NVIDIA GPU is exposed through Dynamic DirectPath I/O.
- VCF Automation/tenancy layer – the namespace, VPC, Transit Gateway connectivity, and resource quotas live here.
- PAIS platform layer – Private AI Services creates and manages its own VKS cluster.
- Model runtime layer – PAIS creates a dedicated GPU worker and runs Qwen using vLLM.
- Consumer layer – VCF Operations connects to the PAIS endpoint, and VMware Intelligent Assist uses the model.
The final request path looks like this:
User
 |
 v
VMware Intelligent Assist
 |
 v
VCF Operations agent / tools
 |
 v
VCF Private AI LLM Provider
 |
 v
https://vcf-pais.vcf.vworld.lab
 |
 v
PAIS Ingress 40.40.40.2:443
 |
 v
Qwen2.5-7B-Instruct / vLLM
 |
 v
PAIS-managed VKS inference worker
 |
 v
small-gpu VM Class
 |
 v
NVIDIA RTX 4000 SFF Ada
The model files are not stored inside the ModelEndpoint itself. They live in Regional Harbor:
192.168.51.7/models/qwen/qwen2.5-7b-instruct:v2The Lab Configuration
Before copying values from the screenshots, here is the complete working configuration so that the names and networks used later make sense.
| Component | Working lab value |
|---|---|
| VCF | 9.1.1 |
| Private AI Services | 3.0 / Model Runtime Only |
| Supervisor | vcf-super |
| PAIS Namespace | vcf-pais-gmtqg |
| Region | test-region-auto |
| Failure Domain / Zone | domain-c9 |
| GPU | NVIDIA RTX 4000 SFF Ada Generation, 20 GB |
| GPU access | Dynamic DirectPath I/O |
| GPU VM Class | small-gpu – 8 vCPU / 32 GiB / 100% memory reservation |
| VKS Control Plane VM Class | best-effort-xlarge |
| Namespace Class | pais-large |
| PAIS VPC | vpc-vcf-pais-72x7u8 |
| PAIS VPC CIDR | 172.55.0.0/24 |
| Private TGW Block | pais-tgw / 172.60.0.0/16 |
| PodVM subnet | 172.60.0.0/27 |
| Connectivity Profile | pais-connectivity-profile |
| Outbound SNAT address | 40.40.40.1 |
| PAIS Ingress VIP | 40.40.40.2:443 |
| Child VKS API VIP | 40.40.40.3:6443 |
| Regional Harbor | 192.168.51.7:443 |
| Storage Class | vworld-cl01-optimal-datastore-default-policy-autoraid |
| Model | Qwen2.5-7B-Instruct |
| Runtime | vLLM |
Do not treat these numbers as universal PAIS sizing.
These are the values that work in my lab. What is reusable is the architecture, the configuration sequence and the dependency chain.
Prerequisites
I assume that the basic VCF platform already exists. Before we begin, verify that you have:
- a healthy VCF 9.1.1 deployment,
- VCF Automation configured,
- a vSphere Supervisor enabled with NSX VPC networking,
- an operational NSX Edge Cluster and Provider Tier-0,
- Avi integrated with the region,
- working DNS and NTP,
- a supported NVIDIA GPU installed in an ESXi host,
- VCF Depot access with entitlement to PAIS 3.0 artifacts,
- a storage policy that can be exposed as a Namespace Storage Class,
- a Linux tools VM from which we can use Docker, Hugging Face CLI and VCF Consumption CLI.
If all of those are in place, we can start.
Part 1 – Turn the Physical GPU into a Resource PAIS Can Consume
Step 1 – Enable Dynamic DirectPath I/O
The first thing we need is not PAIS at all. We need to make the GPU assignable to a virtual machine.
- Open the vSphere Client.
- Go to Hosts and Clusters.
- Select the ESXi host that physically contains the NVIDIA card.
- Open Configure.
- Under Hardware, open PCI Devices.
- Locate the NVIDIA GPU. NVIDIA devices use a vendor ID
0x10DE. - Select the GPU PCI function required for passthrough.
- Enable Passthrough / DirectPath I/O.
- If vSphere requires a host reboot, perform the reboot and wait for the host to return to the Connected state.
Checkpoint: the NVIDIA device must be available for VM assignment before continuing.
Why not attach the GPU to the Supervisor control plane?
Because the control-plane nodes do not run model inference. PAIS creates a separate worker when a GPU-backed ModelEndpoint is deployed. That is the VM that needs the GPU.
Step 2 – Create the small-gpu VM Class
Now create a VM Class that describes the inference worker PAIS can build.
- In the vSphere Client, open Supervisor Management.
- Navigate to Services > VM Service > Manage > VM Classes.
- Click CREATE VM CLASS.
- Use the following values:
| Field | Value |
|---|---|
| Name | small-gpu |
| vCPU | 8 |
| Memory | 32 GiB |
| Memory Reservation | 32768 MiB / 100% |
| PCI Device | NVIDIA RTX 4000 SFF Ada |
| Device Type | Dynamic DirectPath I/O |
| vGPU Profile | Not used |
- Save the VM Class.
- Make it available to the Supervisor/Region that will host the PAIS namespace.
Checkpoint: small-gpu must be visible as an assignable VM Class.
We will later use best-effort-xlarge for the PAIS VKS control plane and small-gpu only for the ModelEndpoint worker.
Part 2 – Give PAIS Enough Namespace Capacity
Step 3 – Create the pais-large Namespace Class
This is one place where a beginner can easily miss an important concept. The Namespace Class is not the PAIS configuration itself. It is the resource envelope that defines what a namespace can consume.
- Log in to VCF Automation.
- Open Manage & Govern.
- Open Namespace Classes.
- Click NEW NAMESPACE CLASS.
- Set the name to
pais-large. - Configure:
| Resource | Value |
|---|---|
| CPU Limit | 150 GHz |
| CPU Reservation | 10 GHz |
| Memory Limit | 128 GB |
| Memory Reservation | 64 GB |
| Storage | 1 TB |
- Add
best-effort-xlargeto the available VM Classes. - Add
small-gpu. - Add
vworld-cl01-optimal-datastore-default-policy-autoraidas the available Storage Class. - Save the Namespace Class.
Checkpoint: the class must expose both the regular VKS class and the GPU-enabled class.

Figure 1. The pais-large Namespace Class exposes both the regular VKS classes and the dedicated small-gpu class, together with the storage policy used by PAIS.
This is important because PAIS needs two very different kinds of compute from the same namespace: ordinary Kubernetes control-plane VMs and a dedicated GPU inference VM.
Part 3 – Understand the PAIS Network Before Configuring It
This section is worth reading even if your network already works, because PAIS uses two different private address spaces and they solve different problems.
The first network: the PAIS-managed VKS VPC
172.55.0.0/24This is where the PAIS-managed Kubernetes nodes live, including the GPU inference worker.
The second network: the Private-TGW PodVM space
pais-tgw: 172.60.0.0/16
allocated pod-default: 172.60.0.0/27
This address space is used by infrastructure components that communicate through the Transit Gateway path.
And then we have three external-looking addresses
40.40.40.1 = outbound SNAT address
40.40.40.2 = PAIS ingress VIP
40.40.40.3 = PAIS-managed VKS API VIP
This distinction matters. 40.40.40.1 is not the PAIS web endpoint. It is the source address used for outbound connectivity.
Step 4 – Enable Provider Outbound SNAT
- Open the VCF Automation provider/enterprise administration view.
- Navigate to VPC Connectivity > External Connections.
- Open the External Connection used by the organization/region.
- Click Edit.
- Open the advanced networking settings.
- Enable Provider Outbound SNAT.
- Select the
external-appSNAT IP Block. - Save the External Connection.

Figure 2. The final External Connection configuration: Provider Outbound SNAT is enabled and the external-app SNAT IP Block is assigned.
The resulting infrastructure path should be:
PAIS PodVM 172.60.0.x
     |
     v
Transit Gateway
     |
     | SNAT
     v
40.40.40.1
     |
     v
Provider Tier-0
Step 5 – Verify the Private Transit Gateway Block
The block used in my lab is:
Name: pais-tgw
CIDR: 172.60.0.0/16
The PAIS namespace receives:
pod-default: 172.60.0.0/27Step 6 – Verify the TGW NAT Rule
Once the namespace exists, verify that the Transit Gateway NAT rule has the expected values:
| Setting | Value |
|---|---|
| Source | 172.60.0.0/27 |
| Destination | Any |
| Action | SNAT |
| Translated Address | 40.40.40.1 |
| Applied To | All Connections |
| Enabled | Yes |

Figure 3. The Transit Gateway NAT rule for the PAIS pod-default Private-TGW subnet.
Step 7 – Add the External Firewall NAT
My VCF lab uses pfSense northbound of NSX. NSX translates the PAIS-managed VKS worker traffic from 172.55.0.x to 40.40.40.1. That means pfSense sees 40.40.40.1, not the original VKS source.
- Log in to pfSense.
- Open Firewall > NAT > Outbound.
- Use Hybrid or Manual Outbound NAT mode if required.
- Create a rule with Source
40.40.40.1/32. - Translate it to the WAN interface address.
- In my lab, the WAN NAT address is
192.168.100.145. - Save the rule and click Apply Changes.
PAIS VKS worker 172.55.0.x
        |
        | NSX SNAT
        v
40.40.40.1
        |
        | pfSense Outbound NAT
        v
192.168.100.145
        |
        v
Internet
Why is Internet access needed?
In a connected deployment the PAIS-managed workers may need to reach NVIDIA, Broadcom/JFrog and Kubernetes-related repositories while the GPU software and model runtime are being prepared.
Do not NAT the whole 40.40.40.0/24 range.
In this design,
40.40.40.2and40.40.40.3are service VIPs. Only40.40.40.1is the outbound SNAT address.
Part 4 – Install Private AI Services 3.0
Step 8 – Verify the Broadcom Registry Token
Before enabling the Supervisor Service, make sure the VCF Depot account is entitled to PAIS 3.0 and can obtain the required OCI registry token.
The important distinction is:
Broadcom account password != Broadcom Registry TokenPAIS runtime images are retrieved from Broadcom package infrastructure, including:
pais-docker.packages.broadcom.comStep 9 – Register / Enable the PAIS Supervisor Service
- Open the vSphere Client.
- Navigate to Supervisor Management > Services.
- Locate Private AI Services.
- If the service is not registered yet, add the PAIS 3.0 Supervisor Service definition. In this lab the definition was
pais-3.0.0.yml. - Use Actions > Manage Service.
- Select the Supervisor used by the region.
- Enable/deploy the service.
- Wait for the PAIS service controller and package reconciliation to complete.
Checkpoint: do not create the actual PAIS configuration while the Supervisor Service itself is still reconciling.
Part 5 – Create the Namespace That Will Host PAIS
Step 10 – Create the Namespace
- Log in to the VCF Automation organization.
- Open Build & Design > Projects.
- Open the project that should host PAIS.
- Open the Namespaces tab.
- Click NEW NAMESPACE.
- Enter the following values:
| Field | Value |
|---|---|
| Name | vcf-pais-gmtqg |
| Namespace Class | pais-large |
| Region | test-region-auto |
| Service Engine Group | se-namespace-test |
| VPC | vpc-vcf-pais-72x7u8 |
| VPC CIDR | 172.55.0.0/24 |
| Private TGW Block | pais-tgw / 172.60.0.0/16 |
| Connectivity Profile | pais-connectivity-profile |
| External SNAT Block | external-app |
- Review the summary.
- Click CREATE.
- Wait until the namespace becomes Ready.
Checkpoint: before continuing, confirm that the namespace sees the correct Storage Class, best-effort-xlarge, and small-gpu.
Part 6 – Configure PAIS Itself
Step 11 – Open Private AI Services in the Namespace
- Open
vcf-pais-gmtqg. - Open the services available to the namespace.
- Select Private AI Services.
- Start the configuration wizard.
Step 12 – Select Model Runtime Only
PAIS can expose more than a simple inference runtime, but for this guide, our goal is to host a local LLM. Select:
Service Capability: Model Runtime OnlyThis is reflected later in the generated configuration, where Agent Builder and Indexing are disabled.
Step 13 – Configure Storage and the VKS Control Plane
| Field | Value |
|---|---|
| Default Storage Class | vworld-cl01-optimal-datastore-default-policy-autoraid |
| VKS Control Plane VM Class | best-effort-xlarge |
This is an important place to avoid a common conceptual mistake: do not select the GPU class for the control plane.
Step 14 – Configure Local Authentication
- Enable the local-user authentication option.
- Create the local PAIS user for the lab.
- Use the FQDN that will later point to the PAIS ingress:
https://vcf-pais.vcf.vworld.labStep 15 – Configure the NVIDIA Runtime
- Open the GPU configuration section.
- Select GPU passthrough / DirectPath mode.
- Select OSS as the GPU driver type.
- The final configuration in this lab uses NVIDIA GPU Operator
25.10.1.
Step 16 – Deploy PAIS
Before submitting the wizard, the important values should be:
Capability:         Model Runtime Only
Storage Class:      vworld-cl01-optimal-datastore-default-policy-autoraid
VKS VM Class:       best-effort-xlarge
GPU Driver Type:    OSS
Authentication:     Local User
Ingress:            LoadBalancer
Click DEPLOY / FINISH.
Now give PAIS time to create its VKS control plane and platform services.
Checkpoint:
PAISConfiguration/default
Ready=True
reason=paisAvailable

Figure 4. Final PAIS Service Configuration. PAIS reports Ready (paisAvailable), uses best-effort-xlarge for the VKS control plane, and exposes the ingress on 40.40.40.2.
What Did PAIS Just Create?
This is the part I always like to verify because it shows how much automation is hidden behind one wizard.
After PAIS becomes Ready, the platform has created or configured:
- a PAISConfiguration object,
- a PAIS-managed VKS cluster,
- load-balanced PAIS services,
- the NVIDIA GPU Operator configuration,
- runtime credentials and service accounts,
- the storage and network plumbing required for future ModelEndpoints.
Step 17 – Verify the Avi Virtual Services
Open Avi and verify the new load-balanced services.
PAIS Ingress:  40.40.40.2:443
VKS API:       40.40.40.3:6443
Harbor:        192.168.51.7:443

Figure 5. Avi Virtual Services after PAIS deployment, including Regional Harbor, the PAIS-managed VKS API and PAIS ingress.
Part 7 – Give PAIS a DNS Name and an API Token
Step 18 – Create the DNS Record
Create:
vcf-pais.vcf.vworld.lab -> 40.40.40.2Verify:
nslookup vcf-pais.vcf.vworld.labStep 19 – Configure the PAIS FQDN
Now make sure the PAIS configuration uses that FQDN as its endpoint/issuer URL. In the final lab configuration, the issuer is:
https://vcf-pais.vcf.vworld.labYou can verify the resulting configuration from the Supervisor:
kubectl get paisconfiguration default \
  -n vcf-pais-gmtqg \
  -o yaml
Look for the configured authentication provider and issuer URL.
Step 20 – Configure Long-Lived API Tokens for the Lab
For the persistent VCF Operations integration, I configured:
expirationDefault = 8760h
expirationMax     = 8760h
That gives the lab a one-year token lifetime. This is convenient for a private test environment; production values should match your security requirements.
Step 21 – Generate the Token
- Open
https://vcf-pais.vcf.vworld.lab. - Log in using the local PAIS user.
- Open the user menu.
- Open API Tokens.
- Create a token.
- Copy it and store it securely.

Figure 6. PAIS User Access with the local account and the configured issuer URL.
Part 8 – Prepare Regional Harbor as the Model Store
Step 22 – Verify Regional Harbor
In this environment, the model registry is the Regional Harbor created by VCF Automation:
VIP:             192.168.51.7:443
Namespace:       svc-harbor-yzt43
Authentication:  db_auth
Project:         models
Visibility:      public
Open Harbor and verify that the models project exists.

Figure 7. Avi topology for the kube-system DNS LoadBalancer used by the PAIS infrastructure.
Step 23 – Trust the Harbor CA on the Tools VM
My tools VM is Rocky Linux. Copy the Harbor CA to the VM and add it to both the OS and Docker trust stores:
sudo cp harbor-ca.crt \
  /etc/pki/ca-trust/source/anchors/harbor-ca.crt

sudo update-ca-trust

sudo mkdir -p /etc/docker/certs.d/192.168.51.7

sudo cp harbor-ca.crt \
  /etc/docker/certs.d/192.168.51.7/ca.crt
Step 24 – Test Harbor Before Uploading Anything
curl https://192.168.51.7/v2/An HTTP 401 Unauthorized without credentials is actually the expected result. It means TLS works, Harbor is reachable, and the registry is waiting for authentication.
Part 9 – Download Qwen2.5-7B-Instruct
Step 25 – Check Disk Space
Do this before downloading the model:
df -hQwen is much larger than a tiny smoke-test model. In my tools VM, /home was expanded to roughly 108 GB, with about 90 GB free before the final model workflow.
Step 26 – Download Qwen from Hugging Face
mkdir -p ~/pais/models/Qwen2.5-7B-Instruct

hf download \
  Qwen/Qwen2.5-7B-Instruct \
  --local-dir ~/pais/models/Qwen2.5-7B-Instruct

cd ~/pais/models/Qwen2.5-7B-Instruct
Verify the local content:
du -sh .
ls -lah
Part 10 – Convert the Local Model into a PAIS Model Artifact
Step 27 – Log in to the Harbor Model Store
vcf pais models repo login 192.168.51.7 \
  --username admin \
  --ca-cert-path ~/pais/certs/harbor-ca.crt
Step 28 – Push Qwen
Use a lowercase repository/model name:
vcf pais models push \
  --modelStore 192.168.51.7/models \
  --modelName qwen/qwen2.5-7b-instruct \
  --tag v2
The final model reference used by PAIS is:
192.168.51.7/models/qwen/qwen2.5-7b-instruct:v2The correct Qwen artifact in the lab is approximately:
Tag:     v2
Size:    ~14.20 GiB
Layers:  42
Step 29 – Add Harbor CA Trust to PAIS
- Return to the PAIS UI.
- Open CA Trust Bundles.
- Create a bundle named
harbor. - Add the Regional Harbor CA certificate.
- Save the configuration.
- Wait until PAIS returns to Ready state.
Checkpoint: PAIS must trust Harbor before the ModelEndpoint worker can download the model.
Part 11 – Deploy Qwen2.5-7B-Instruct
Step 30 – Open Model Runtime
- Open the PAIS service in
vcf-pais-gmtqg. - Open the Model Runtime tab.
- Click NEW MODEL ENDPOINT.
Step 31 – Configure the Model Identity
| Field | Value |
|---|---|
| Model URL | 192.168.51.7/models/qwen/qwen2.5-7b-instruct |
| Image Tag | v2 |
| Routing Name | qwen2.5-7b-instruct |
| Display Name | qwen2.5-7b-instruct |
| Model Type | Completions |
| Engine | vLLM |
The Routing Name is especially important because clients will use it to address the model through the API.
Step 32 – Configure the GPU Worker
| Field | Value |
|---|---|
| VM Class Type | GPU |
| VM Class | small-gpu |
| Instances | 1 |
| Storage Class | vworld-cl01-optimal-datastore-default-policy-autoraid |
| Registry Secret | Empty in this lab because the Harbor project is public |
Step 33 – Enable vLLM Tool Calling
This is one of the most important details in the entire Qwen configuration.
Enable Advanced Customization and add:
--enable-auto-tool-choice
--tool-call-parser=hermes
Why? Because VMware Intelligent Assist asks the LLM for natural-language text. The model must also participate in tool-oriented workflows. These vLLM options enable the Qwen runtime to support that behavior.

Figure 8. Qwen2.5-7B-Instruct ModelEndpoint configuration with Advanced Customization enabled.
Step 34 – Review and Deploy
Before clicking Deploy, verify:
Model:
192.168.51.7/models/qwen/qwen2.5-7b-instruct:v2

Engine:
vLLM

Worker:
small-gpu

Instances:
1

Arguments:
--enable-auto-tool-choice
--tool-call-parser=hermes
Click DEPLOY.

Figure 9. Final review of the Qwen ModelEndpoint: Qwen v2, vLLM, small-gpu and tool-calling arguments.
The endpoint will initially be Pending. That is expected.

Figure 10. The Qwen ModelEndpoint while PAIS creates and prepares the dedicated GPU worker.
What Happens Behind the Scenes When You Click Deploy?
This is where PAIS becomes really interesting.
A ModelEndpoint deployment does not simply start a container on an existing node. PAIS orchestrates a chain of platform actions:
- Cluster API creates an inference-worker Machine.
- VM Operator creates the corresponding VM.
- The VM uses the
small-gpuclass. - Dynamic DirectPath I/O attaches the physical NVIDIA GPU.
- NVIDIA GPU Operator prepares the node.
- Storage is attached.
- The model artifact is downloaded from Regional Harbor.
- The vLLM runtime is started.
- The model is exposed through the PAIS API layer.
That is a lot of infrastructure hidden behind one ModelEndpoint wizard.
Part 12 – Verify the GPU Worker Instead of Just Waiting for the UI
Step 35 – Connect to the PAIS-managed VKS Cluster
export KUBECONFIG=/tmp/pais-vks-kubeconfig

kubectl get nodes -o wide
kubectl get pods -A -o wide
You should eventually see a dedicated worker created for Qwen.
Step 36 – Confirm Kubernetes Can See the GPU
kubectl get node <qwen-gpu-node> -o json | jq '{
  capacity: .status.capacity["nvidia.com/gpu"],
  allocatable: .status.allocatable["nvidia.com/gpu"]
}'
Expected:
{
  "capacity": "1",
  "allocatable": "1"
}
This is the point where we know that the GPU is not only attached to the VM, but also advertised as a Kubernetes schedulable resource.
Step 37 – Verify the ModelEndpoint from the Supervisor
kubectl get paisconfiguration default \
  -n vcf-pais-gmtqg \
  -o json | jq '.status.conditions'

kubectl get modelendpoints \
  -n vcf-pais-gmtqg

kubectl get modelendpoint <qwen-endpoint-name> \
  -n vcf-pais-gmtqg \
  -o json | jq '.status'
You can also inspect what PAIS created underneath:
kubectl get machines.cluster.x-k8s.io \
  -n vcf-pais-gmtqg \
  -o wide

kubectl get virtualmachines \
  -n vcf-pais-gmtqg \
  -o wide
Checkpoint: do not continue until the ModelEndpoint becomes Available.
Part 13 – Test PAIS Before Involving VCF Operations
This is an important troubleshooting habit: first prove the model works through PAIS itself. Only then add VCF Operations.
Step 38 – Export the API Token
export PAIS_API_KEY='<your-api-token>'Step 39 – List the Available Models
curl -k \
  "https://vcf-pais.vcf.vworld.lab/api/v1/compatibility/openai/v1/models" \
  -H "Authorization: Bearer $PAIS_API_KEY" \
  -H "Content-Type: application/json"
Qwen should appear in the response.
Step 40 – Send a Chat Completion
curl -k \
  "https://vcf-pais.vcf.vworld.lab/api/v1/compatibility/openai/v1/chat/completions" \
  -H "Authorization: Bearer $PAIS_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "qwen2.5-7b-instruct",
    "messages": [
      {
        "role": "user",
        "content": "Explain VMware Cloud Foundation in one sentence."
      }
    ],
    "max_tokens": 200,
    "temperature": 0
  }'
If this returns a valid response, the entire path from the client, through PAIS ingress, to vLLM and the GPU-backed Qwen model is working.
Part 14 – Connect the Local Model to VMware Intelligent Assist
Now that PAIS works independently, we can add VCF Operations as the consumer.
Step 41 – Enable the Required VCF Operations Components
If the environment does not already have the required management components, verify Log Management first:
- Open VCF Operations.
- Navigate to Build > Lifecycle > VCF Management.
- Use Add Component if Log Management is not yet deployed.
- Wait until the component becomes healthy.
Step 42 – Activate Intelligent Assist and Advanced Configuration
- Open Extensions > Extension Management.
- Activate VMware Intelligent Assist.
- Activate Advanced Configuration.
- Open Extensions > Advanced Configuration and enable Intelligent Assist.
Step 43 – Add VCF Private AI as an LLM Provider
- Navigate to Extensions > Advanced Configuration > LLM Providers.
- Click ADD.
- Select VCF Private AI.
- Use the PAIS endpoint:
https://vcf-pais.vcf.vworld.lab/- Paste the PAIS API token.
- Save the provider.
- Wait for Health to become Healthy.
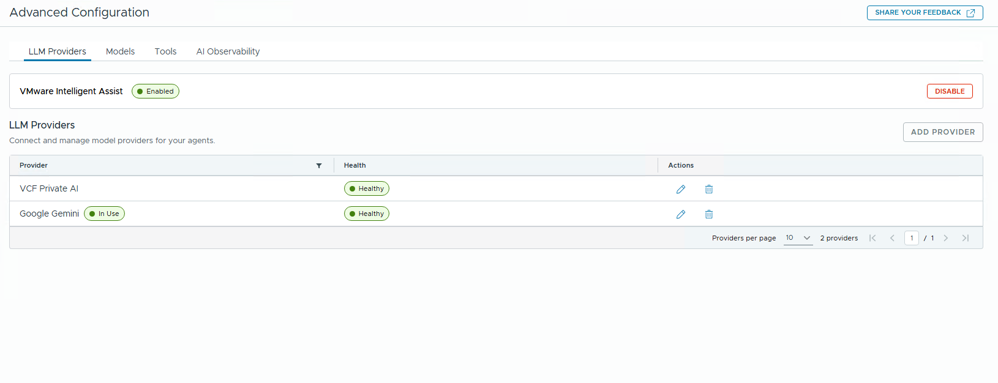
Figure 11. VCF Operations Advanced Configuration with the VCF Private AI provider reporting Healthy.
Step 44 – Select Qwen
- Open Extensions > Advanced Configuration > Models.
- Select the VCF Private AI provider.
- Select
qwen2.5-7b-instruct. - Save the configuration.
At this point, the local model is no longer just a PAIS endpoint. It is the LLM behind VMware Intelligent Assist.
Part 15 – Prove That It Is Using Real VCF Data
A generic question like “What is VMware Cloud Foundation?” is not a good final test. Any LLM could answer that from its training data.
Instead, ask something that requires VCF Operations to call its own tools.
Step 45 – Ask for the vCenter Inventory
List my vCentersIn the working lab, the response included:
vcf-vcsa.vcf.vworld.lab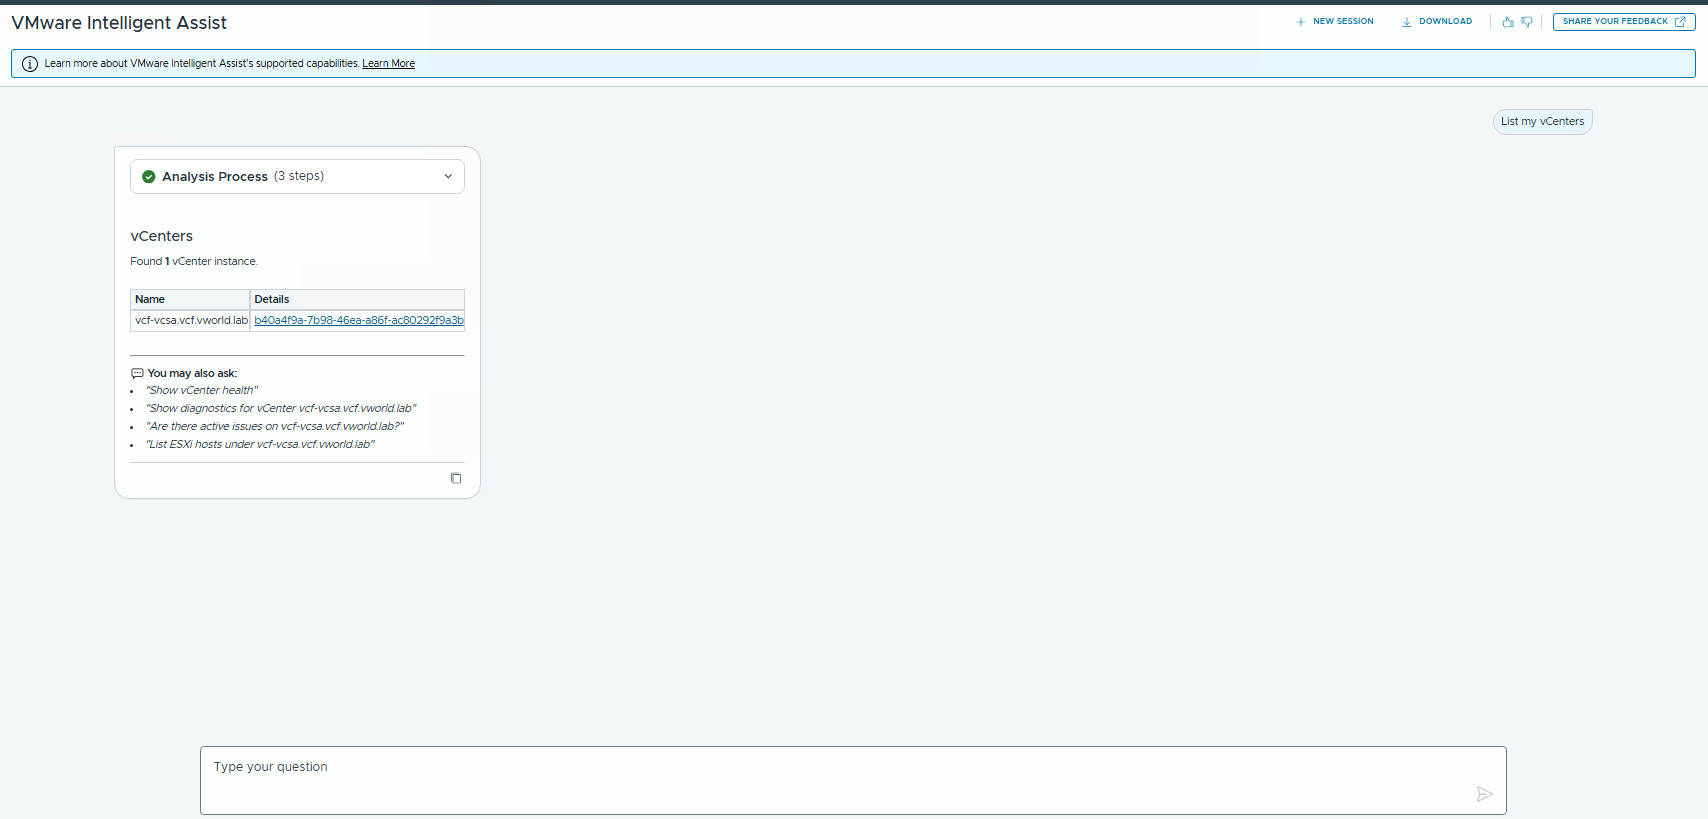
Figure 12. VMware Intelligent Assist returning the live vCenter instance through the local Qwen model.
Step 46 – Ask for the ESXi Hosts
Show me the ESXi hostsIntelligent Assist returned the three ESXi hosts monitored by VCF Operations.
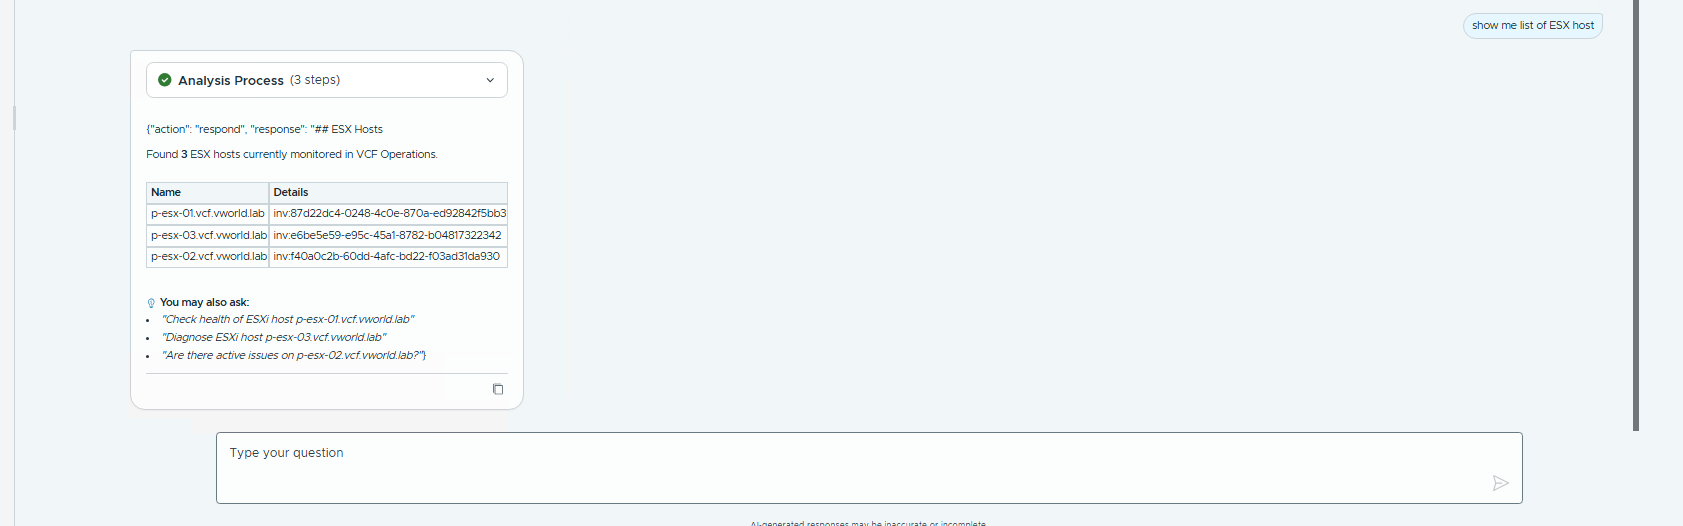
Figure 13. Qwen-backed Intelligent Assist returning the ESXi hosts monitored by VCF Operations.
Step 47 – Ask a More Exploratory Inventory Question
A broader inventory request also triggered the VCF Operations inventory workflow and returned resource types related to the selected vCenter.
This is the result I wanted from the beginning of the lab:
Local Qwen model
     +
VCF Operations live tools
     =
VMware Intelligent Assist answering questions about my real VCF environment
Final Verification Checklist
- PAIS Supervisor Service is healthy.
PAISConfiguration/defaultreportsReady=True / paisAvailable.ModelEndpointPrerequisitesMet=True.GPUOperatorReady=True.- Avi exposes PAIS ingress and the child VKS API.
- Provider Outbound SNAT is enabled.
- TGW NAT translates
172.60.0.0/27to40.40.40.1. - The external firewall/NAT gives
40.40.40.1Internet access. - Regional Harbor is reachable and trusted.
- Qwen
v2exists in Harbor. - The GPU worker advertises
nvidia.com/gpu=1. - The Qwen ModelEndpoint is
Available. - The PAIS OpenAI-compatible API returns Qwen.
- The VCF Private AI provider is
Healthy. - Qwen is selected as the VCF Operations model.
- Intelligent Assist returns live vCenter and ESXi inventory.
Conclusion
We started with a physical NVIDIA GPU sitting inside an ESXi host. We ended with Qwen2.5-7B-Instruct running on that GPU, exposed by VCF Private AI Services through an OpenAI-compatible endpoint, and consumed by VMware Intelligent Assist.
The most interesting part is everything VCF builds in between.
The GPU is exposed with Dynamic DirectPath I/O. The namespace defines the compute and storage envelope. VCF Automation provides the VPC and Transit Gateway connectivity. PAIS creates the VKS platform. Cluster API and VM Operator create the inference worker. NVIDIA GPU Operator prepares the GPU. Regional Harbor stores the model. vLLM serves it. VCF Operations finally consumes the model together with live operational tools.
From an infrastructure perspective, that is a surprisingly deep automation chain.
From the consumer perspective, it becomes one private AI endpoint.
And that is probably the best way to understand what Private AI Services adds to VMware Cloud Foundation: it does not remove the complexity of running AI infrastructure – it packages and automates that complexity into something the platform can deliver as a service.